AI People Search Benchmark 2026: Wrangle vs. Exa, Juicebox & More
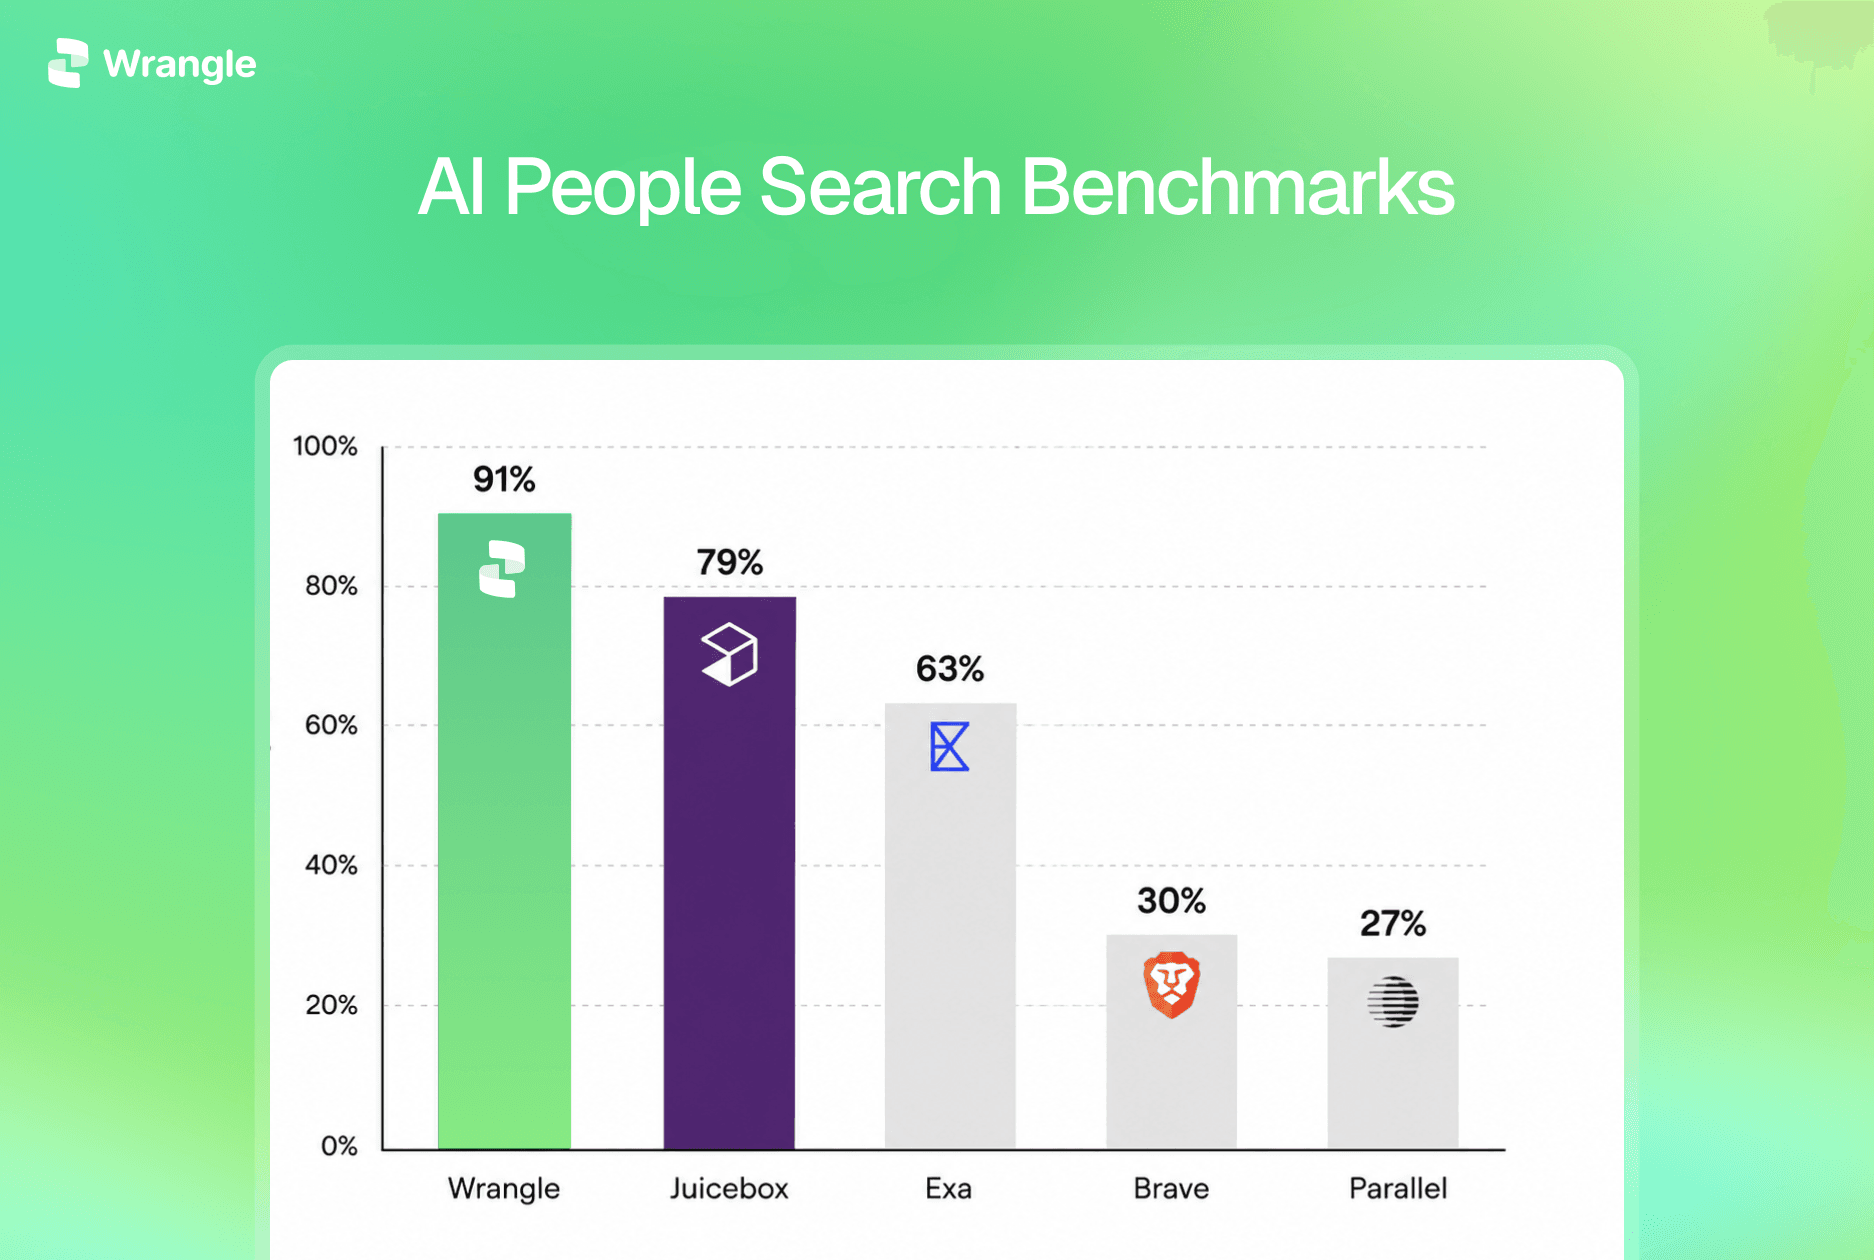
Recruiting software vendors describe their products as "AI-powered," "intelligent," and "precision-driven" without publishing results on a shared query set that anyone can reproduce or contest. SCOUT (Sourcing and Candidate Understanding Test) is how Wrangle publishes its results: by running against established benchmarks with defined scoring protocols, shared query sets, and maintainer-published leaderboards, and reporting the numbers.
Two benchmarks are used here. The Exa People Search Benchmark tests hit rate and precision across 1,400 natural-language sourcing queries. PeopleSearchBench (maintained by LessieAI) scores on a composite of relevance precision, effective coverage, and information utility across a recruiting-specific query set. Where a competitor's result appears on the maintainer's published leaderboard, it is labeled as such. Where a competitor self-reported a number that is not on the maintainer's leaderboard, it is labeled vendor-reported. Numbers labeled vendor-reported should be treated as directional until independently confirmed.
Figure 01: Exa People Search Benchmark
The Exa People Search Benchmark runs 1,400 natural-language sourcing queries against a fixed candidate pool. R@1 measures whether the correct candidate appears as the first result. R@10 measures whether the correct candidate appears within the first ten results. Macro precision measures the share of returned candidates that are relevant across all queries.
Deep is the highest-quality search, Normal is the default high-quality search, and Turbo is the fastest search. The homepage's Exa precision and R@10 cards use the Deep results and round them to one decimal place. Average times are approximate and can vary with the query and request conditions.
Competitor status on this benchmark:
Exa's result comes from the maintainer-published leaderboard, while the three Wrangle mode figures come from Wrangle's evaluation runs. Juicebox and Metaview report precision figures from their own Exa-derived runs; those numbers do not appear on Exa's maintainer-published leaderboard and should not be treated as directly verified leaderboard results.
Figure 02: PeopleSearchBench
PeopleSearchBench is maintained by LessieAI. The homepage reports both the benchmark's overall score and its recruiting-category score. The results below are from Wrangle's Turbo evaluation run and use the same versioned benchmark data as the homepage and agent-readable site copy.
Overall
Recruiting category
The homepage rounds these scores to one decimal place. The extra digit in the tables preserves the precision available in the shared benchmark-data source; it does not represent a different result.
What SCOUT does not measure
Candidate search quality is one dimension of a recruiting platform. SCOUT does not measure outreach deliverability or response rates, scheduling and interview coordination, ATS and CRM automation, diversity sourcing compliance, or time-to-hire outcomes. Those capabilities matter and vary across the platforms listed here. This benchmark measures one thing: when a system is asked to find a candidate, how often does it find the right one.